# Where invalid rows go
Setup: the demo's `Orders` schema, which every example on this page uses
``` python
import dagster as dg
import dataframely as dy
import polars as pl
import dagster_dataframely as dd
from dagster_dataframely_demo.schema import Orders
from dagster_dataframely_demo._data import storefront_orders
from dagster_polars import PolarsParquetIOManager
@dg.asset
def raw_orders() -> pl.DataFrame:
return storefront_orders()
```
`quarantine=True` is the whole setup. There is no directory to configure and no second asset to declare.
**The asset's own IO manager writes the invalid rows**, under the asset's key with `_quarantine` added to the end. It writes the quarantine of `analytics/orders` to `analytics/orders_quarantine`. This works with any IO manager that stores by asset key ([ADR-0006](https://github.com/ozanozbeker/dagster-dataframely/blob/main/docs/pre-1.0.md#adr-0006-the-assets-own-io-manager-writes-the-quarantine)).
The same declaration writes the quarantine to a different place under each IO manager:
``` python
@dd.asset(Orders, quarantine=True)
def orders(raw_orders: pl.DataFrame) -> pl.DataFrame:
return raw_orders
```
| IO manager | where it writes the invalid rows |
|----|----|
| `PolarsParquetIOManager` | `orders_quarantine.parquet`, in the same directory as `orders.parquet` |
| `DuckDBPolarsIOManager` | the table `orders_quarantine`, in the same schema as `orders` |
The first is a `UPathIOManager` and the second is a `DbIOManager`. Nearly every first-party IO manager subclasses one of the two.
The quarantine has the original columns, then one `String` rule column per rule, with `valid`, `invalid` or `unknown` in each row. A rule column takes its rule's name, so it matches the check's name only at the default `rule` granularity. At `column` or `schema` granularity, use the rule column, not a check, to find the rows that failed a rule. Check samples have at most `max_failure_samples` rows per rule, so the rule columns are the only complete record of which rules each row failed.
The table's materialization has the quarantine address, the number of invalid rows, and which sets of rules they failed together. See [What a run produces](what-a-run-produces.md).
**A partitioned asset on a database IO manager needs `partition_expr`.** `DbIOManager` raises an error without it, so you already set it for the asset's own table. The quarantine write uses the same value.
**`quarantine=True` adds a `context` parameter to the asset**, whether or not the decorated function declares one. The package needs the context to write the quarantine. So direct invocation of the asset needs a `dg.build_asset_context()` as the first argument. See [Testing an asset](testing-an-asset.md). An asset without a quarantine keeps the signature you wrote.
# The quarantine is not an asset
It is a record of a run. It is not in the asset graph, so no asset can depend on it until you add it with [quarantine_spec](../reference/quarantine_spec.md#dagster_dataframely.quarantine_spec):
``` python
defs = dg.Definitions(
assets=[raw_orders, orders, dd.quarantine_spec(Orders, orders)],
resources={"io_manager": PolarsParquetIOManager(base_dir="data/warehouse")},
)
```
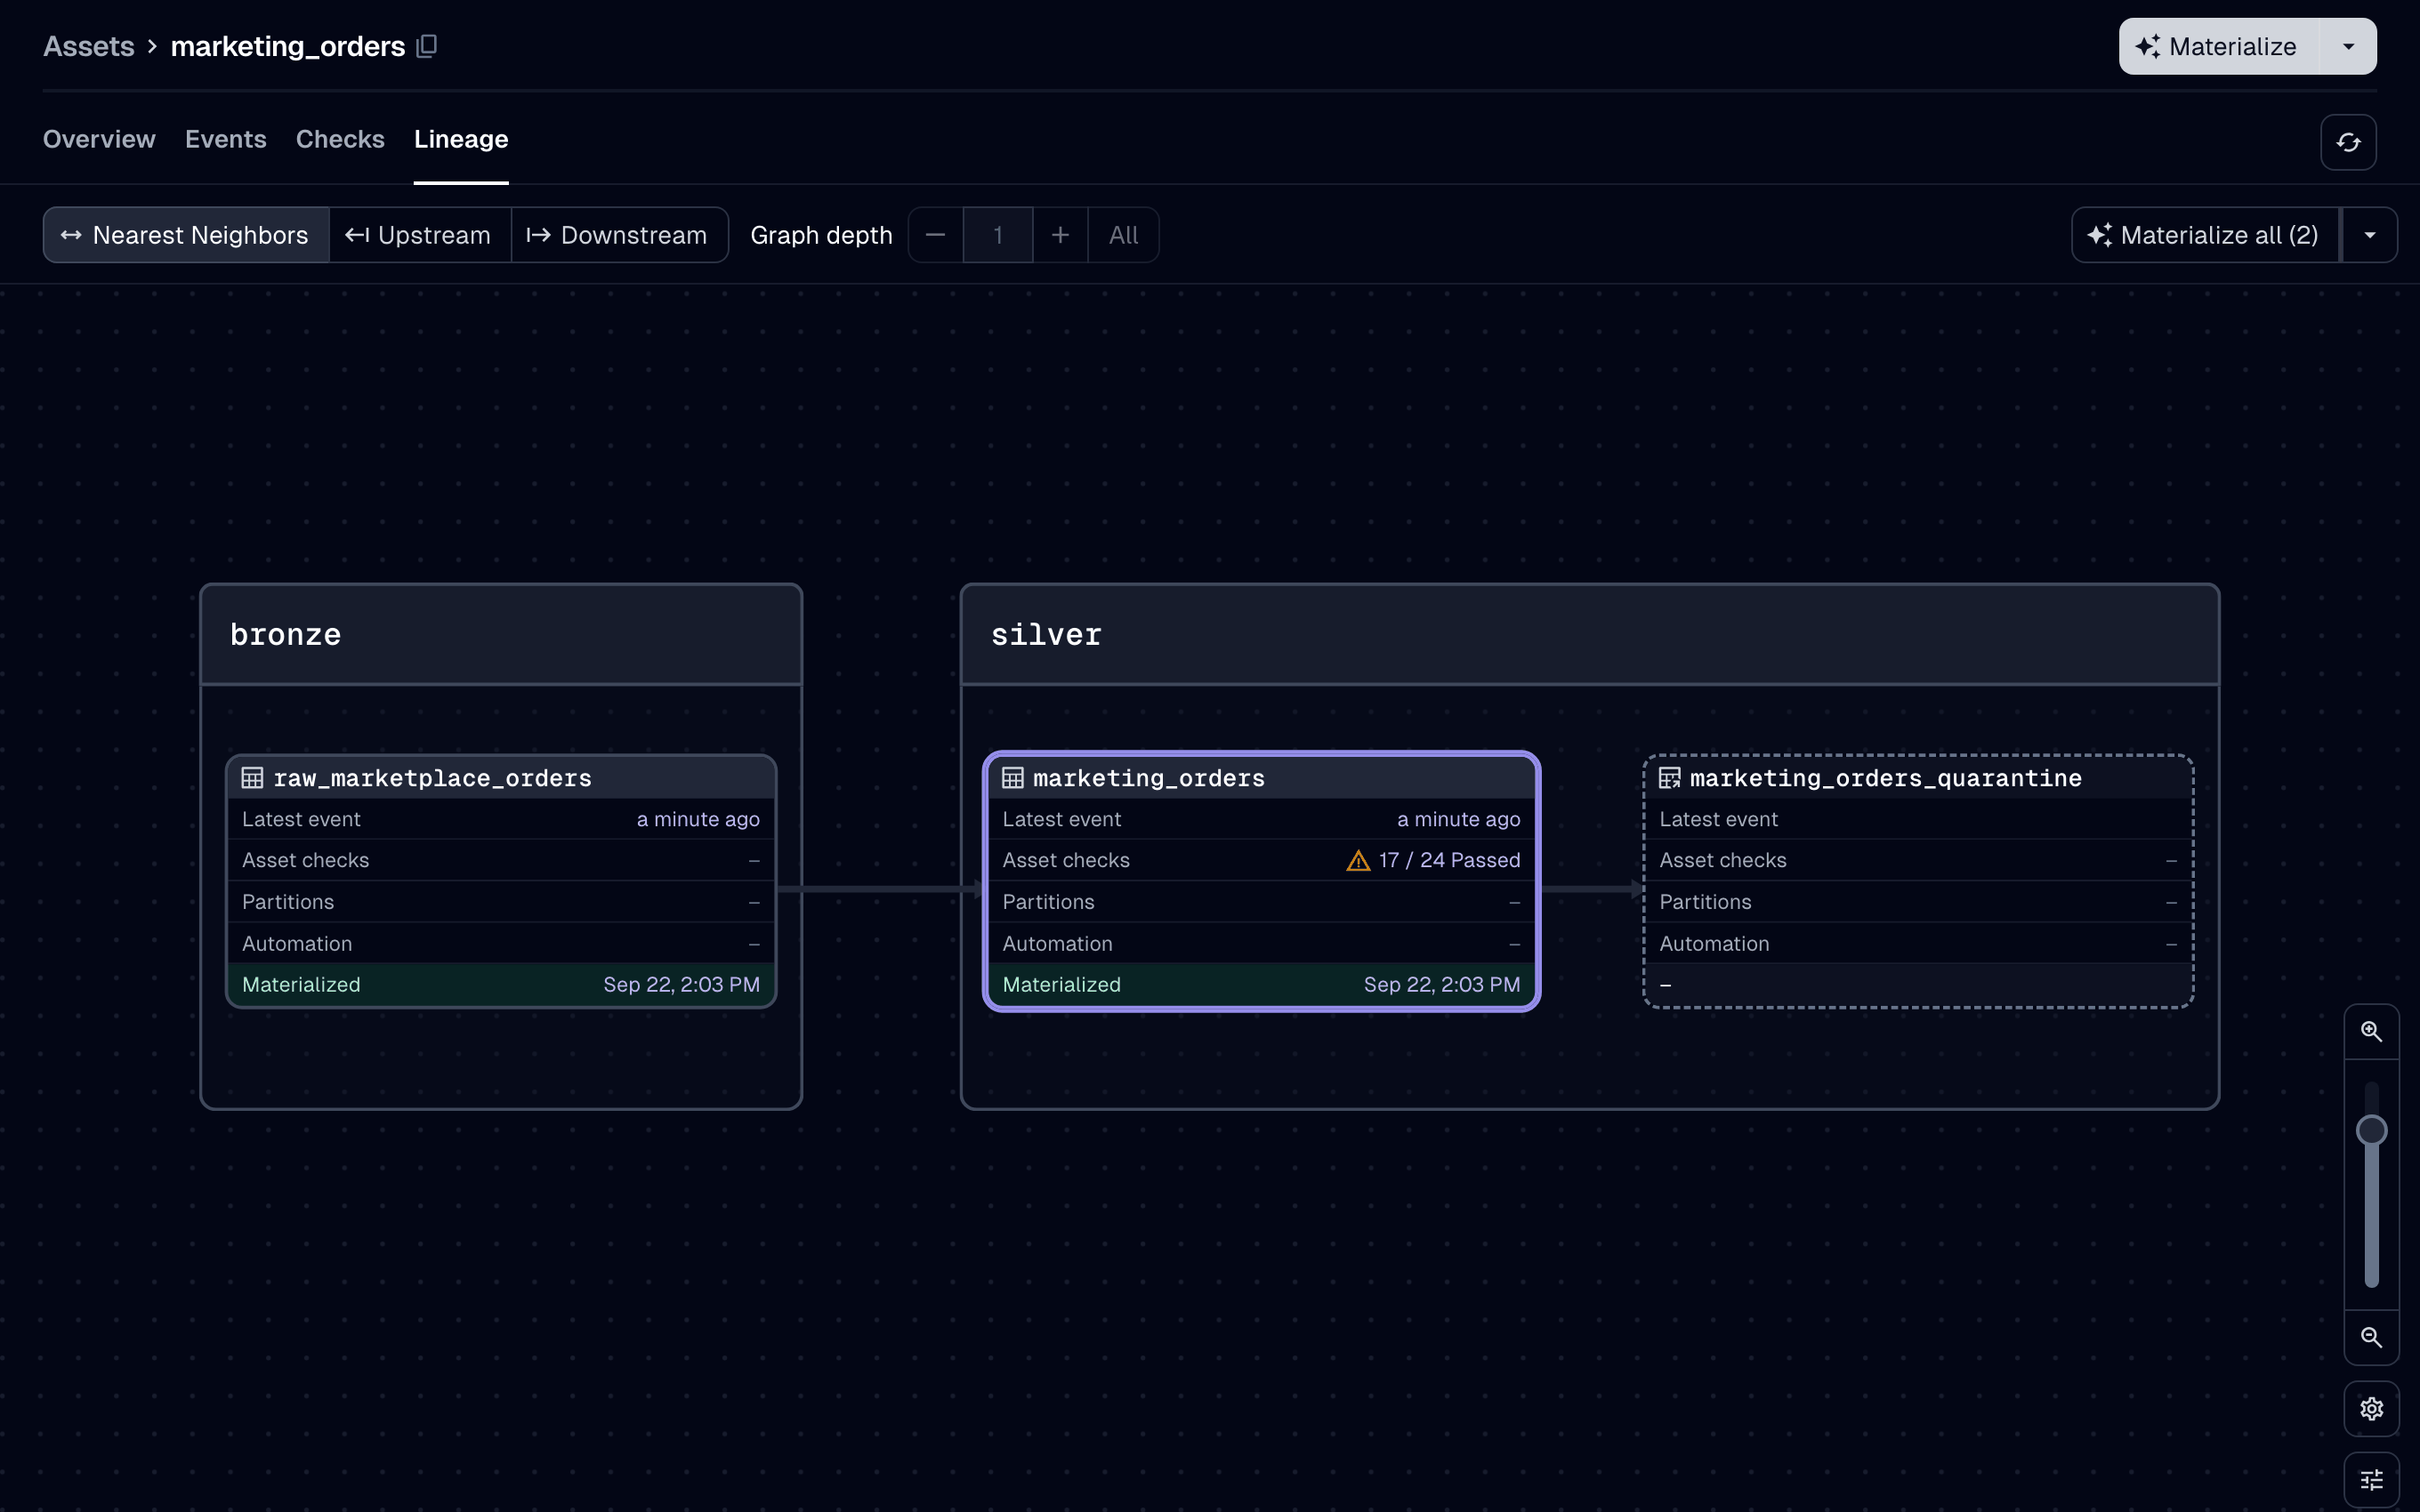
The lineage view shows the quarantine's node. Its one edge comes from marketing_orders, the asset with quarantine=True, not from the upstream raw_marketplace_orders. The node has a dashed border because nothing materializes it.
[quarantine_spec](../reference/quarantine_spec.md#dagster_dataframely.quarantine_spec) returns a `dg.AssetSpec` keyed `orders_quarantine` that depends on `orders` and has its own Columns tab. It has no compute function, because the decorator already writes the rows. The IO manager that wrote the rows also loads them for a downstream asset that names the quarantine as an input.
**The quarantine's Columns tab has no column constraints.** It lists the schema's columns with their dtypes, descriptions and tags, then one `String` column per rule. The invalid rows can fail any of the schema's constraints, so a `not null` on a column full of nulls would be false. The primary key is absent too, because the writer writes rows with a duplicate key to the quarantine.
Pass [quarantine_spec](../reference/quarantine_spec.md#dagster_dataframely.quarantine_spec) the asset definition, and the spec uses its partitions. Pass an asset key instead, and set the partitions with `partitions_def=`. Passing both an asset definition and `partitions_def=` raises `dg.DagsterInvariantViolationError`.
**The quarantine never receives a materialization event, even with a spec.** If you want to automate on invalid rows, see [Automation](partitioning.md#automation).
# `quarantine_dir` is for calling, not running
Direct invocation has no step, so there is no IO manager to write the invalid rows. Instead, [file_writer](../reference/wiring.file_writer.md#dagster_dataframely.wiring.file_writer) writes them under the directory `DAGSTER_DATAFRAMELY_QUARANTINE_DIR` sets. A run does not use this directory.
``` bash
DAGSTER_DATAFRAMELY_QUARANTINE_DIR=/tmp/quarantine
```
The package reads the directory when it writes the invalid rows, not when the module imports. So a `monkeypatch.setenv` in a test takes effect even though Python imported the module that defines the asset earlier. A call where every row is valid never reads it.
If the variable is unset, a call with invalid rows raises [QuarantineDirError](../reference/errors.QuarantineDirError.md#dagster_dataframely.errors.QuarantineDirError). There is no default directory.
There is no per-asset override.
Under that directory, the file path follows `UPathIOManager`'s layout, built from the asset key and the partition key:
``` text
//.../_quarantine.parquet
//.../_quarantine/.parquet
```
Each partition is a separate file in a `_quarantine/` directory, so a backfill of one partition rewrites one file. The file is always parquet, so it keeps every dtype the schema declares.
The package formats a multi-partition key as its dimension keys joined by `/`, in dimension-name order. It escapes a partition key containing `..` or a leading `/`, instead of rejecting it, so no partition can write a file outside `quarantine_dir`.