import dataframely as dy
import polars as pl

import dagster_dataframely as dd


class Customers(dy.Schema):
    """A storefront customer account."""

    customer_id = dy.String(primary_key=True, description="Account identifier.")
    email = dy.String(nullable=False, description="Where receipts are sent.")
    lifetime_value = dy.Float64(nullable=False, min=0.0, description="Spend to date.")


@dd.asset(Customers)
def customers(raw_customers: pl.DataFrame) -> pl.DataFrame:
    """Validate the storefront's customer accounts."""
    return raw_customers
dagster-dataframely
A Dataframely integration for Dagster.
Links
AI / Agents
Developers
Community
Full license Apache-2.0
Meta
Requires: Python >=3.12
Package Info
Dataframely validates Polars frames against a schema. Dagster has two built-in places to show a schema: the Columns tab and asset checks. dagster-dataframely attaches a Dataframely schema to a Dagster asset, so you declare a table once and Dagster shows it in both places.
That is the whole integration. Every Python block on this page comes from the demo pipeline, and every image is a screenshot of it. The images show assets that use its thirteen-column Orders schema. From that one declaration you get:
The catalog’s Columns tab, filled in before the asset first runs: dtypes, descriptions, nullability, uniqueness, the primary key at table level, and every other column constraint beside its column.
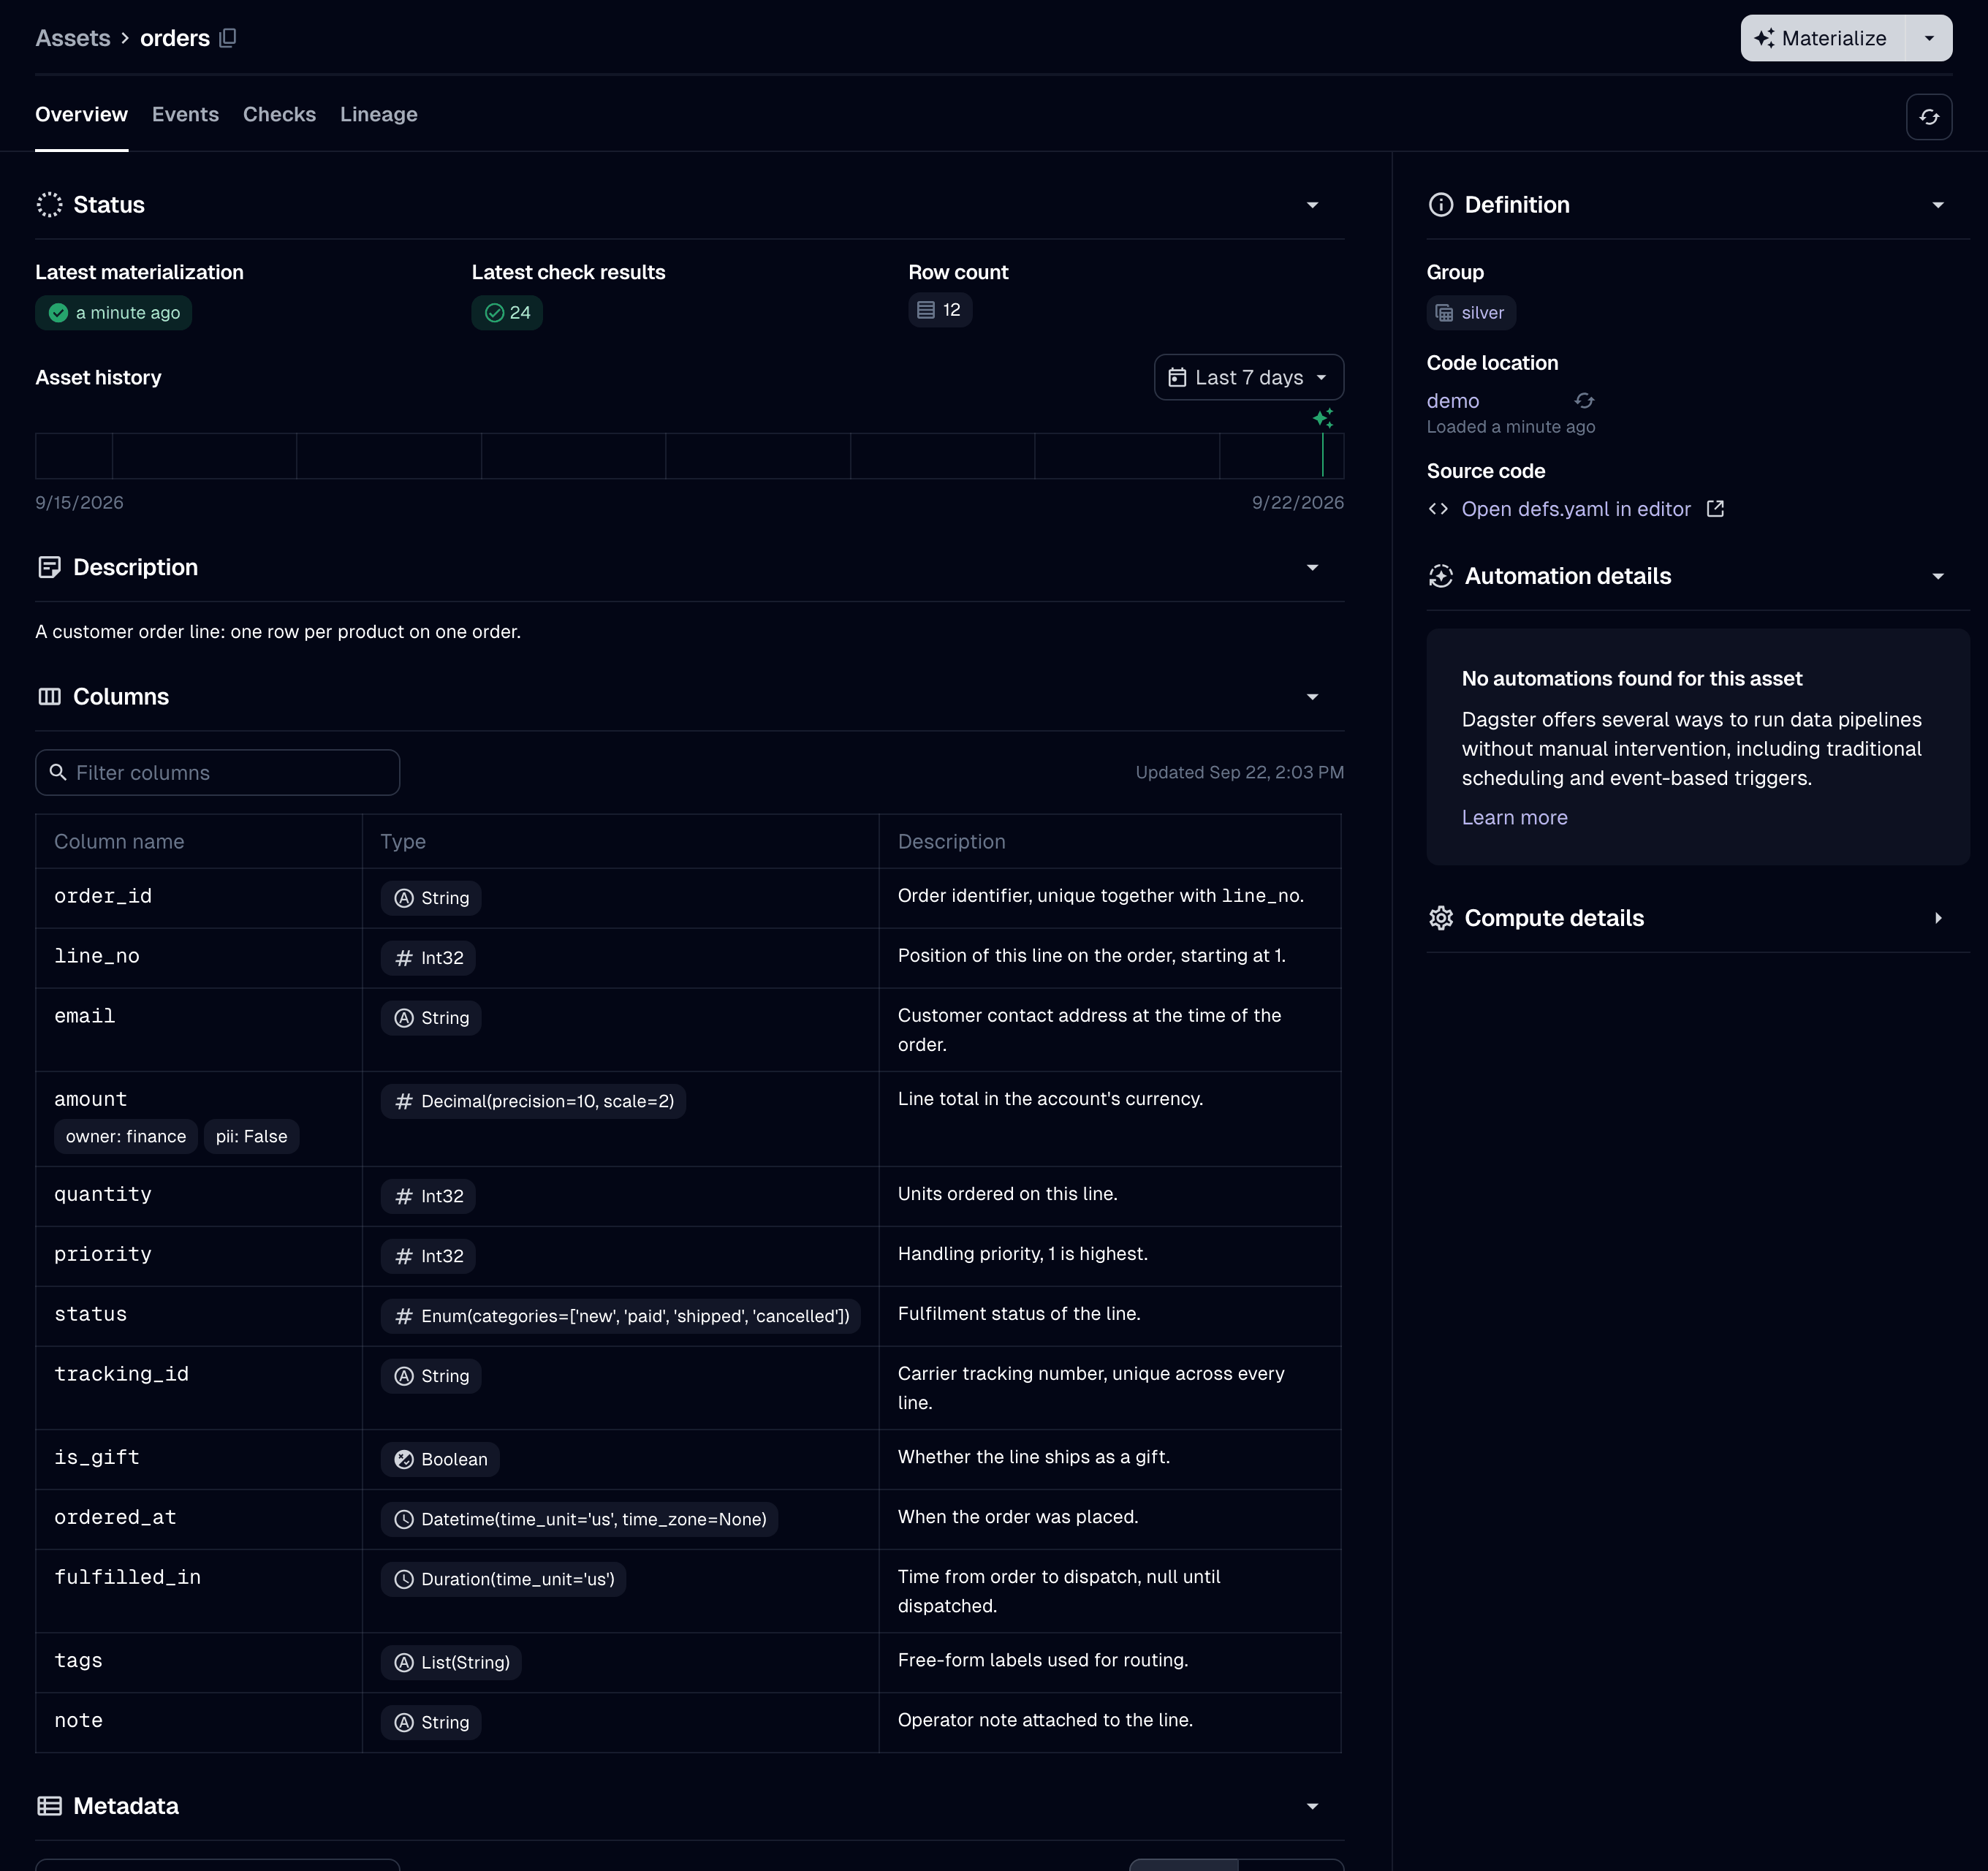
The catalog’s Columns tab for orders, filled from the schema: all thirteen columns with their dtypes and descriptions, and the column tags onamount, declared throughmetadata=.One asset check per Dataframely rule, and each check has its own pass/fail history.
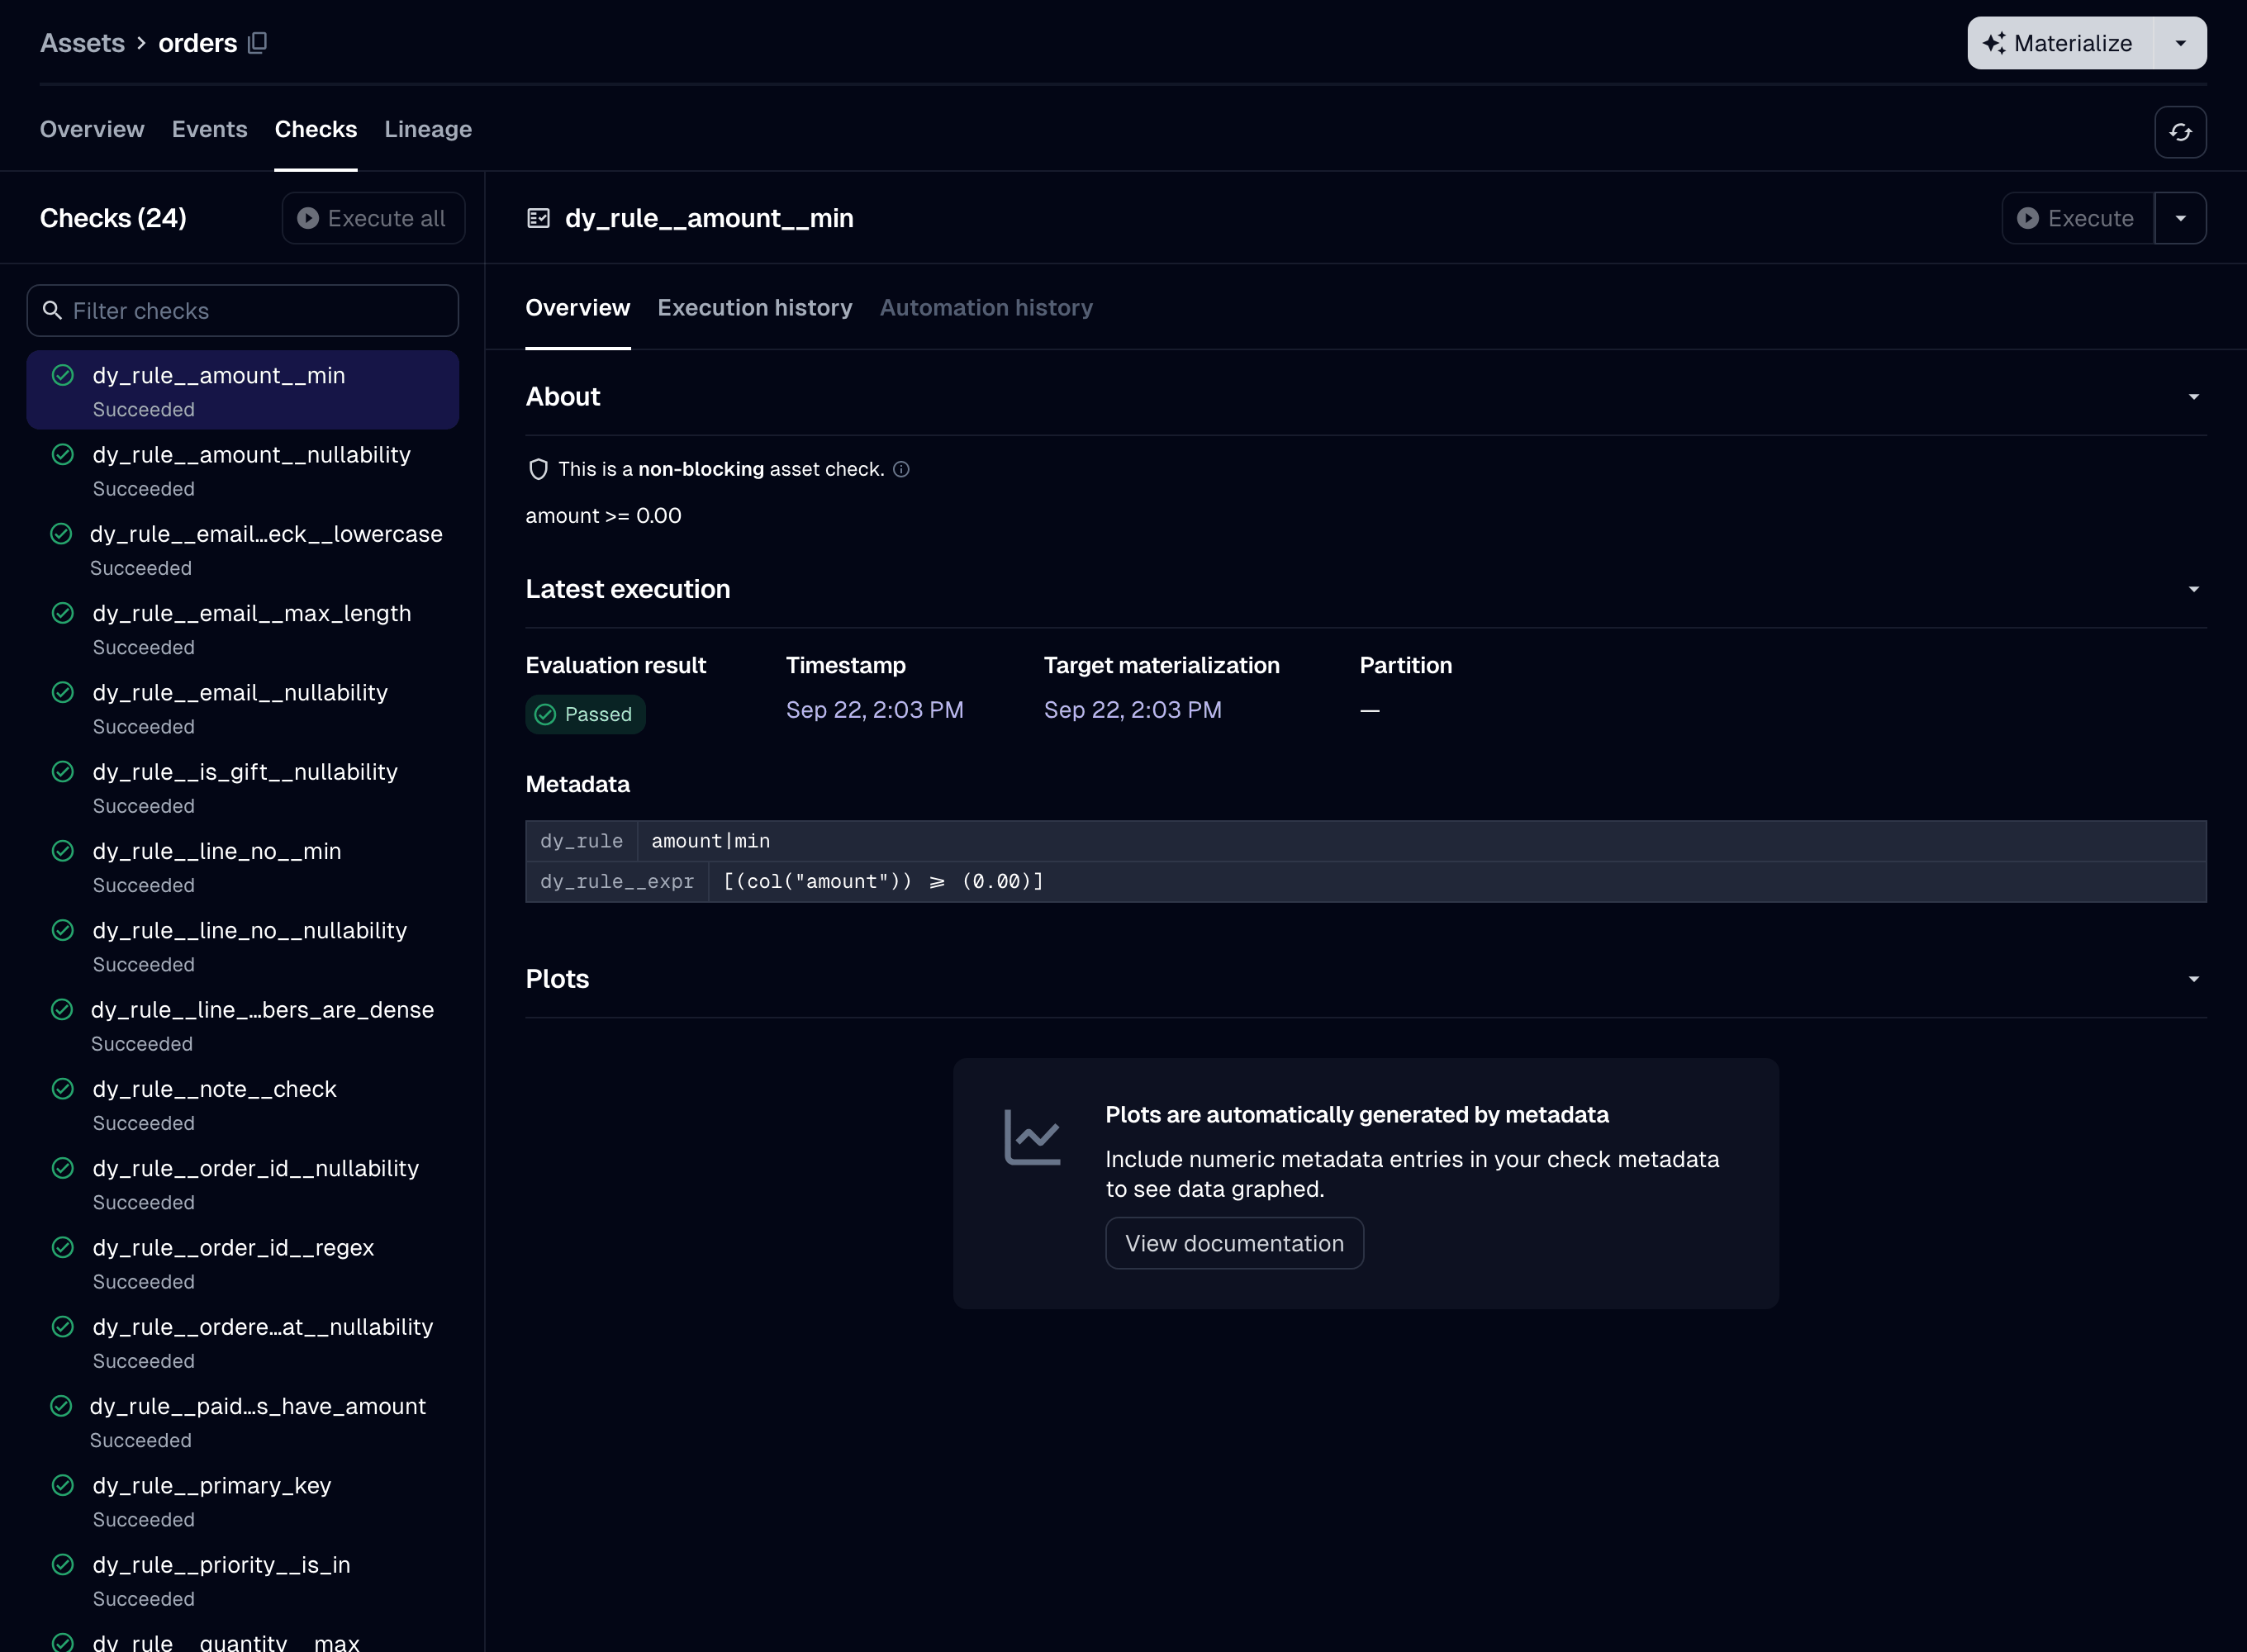
The Checks tab after a run with no failing rows, at the default granularity: one check per rule, each with its own history. The selected check’s description is its rendered constraint, and its metadata has the rule’s name and expression. A blocking column-schema check that compares the frame’s columns and dtypes with the schema’s, before
Schema.filterruns.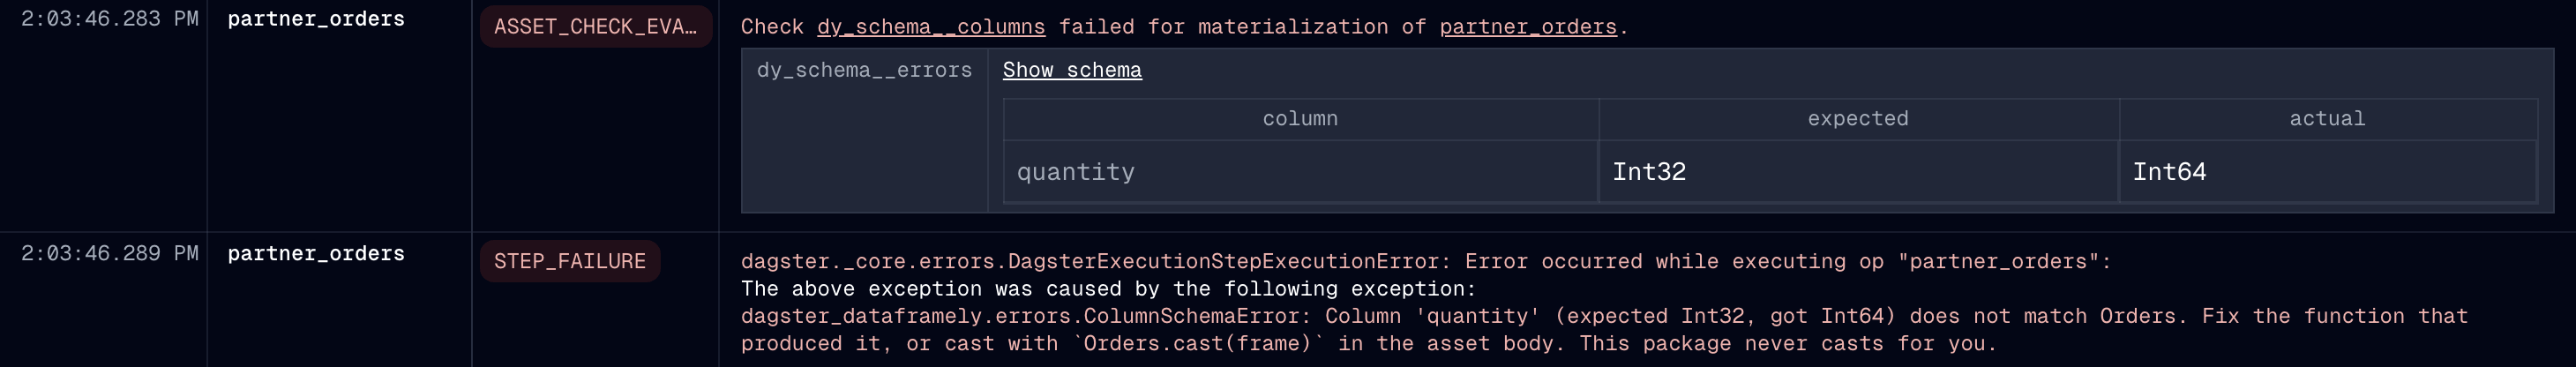
A run log where the quantitycolumn isInt64. The failingdy_schema__columnscheck hasdy_schema__errors, which shows the expected and actual dtype. The step failure below it names the same column in the ColumnSchemaError message.A quarantine for invalid rows, if you declare one. With
quarantine=True, a run with invalid rows writes them to a quarantine next to the table, writes the valid rows to the table, and succeeds. The run still fails when every row is invalid.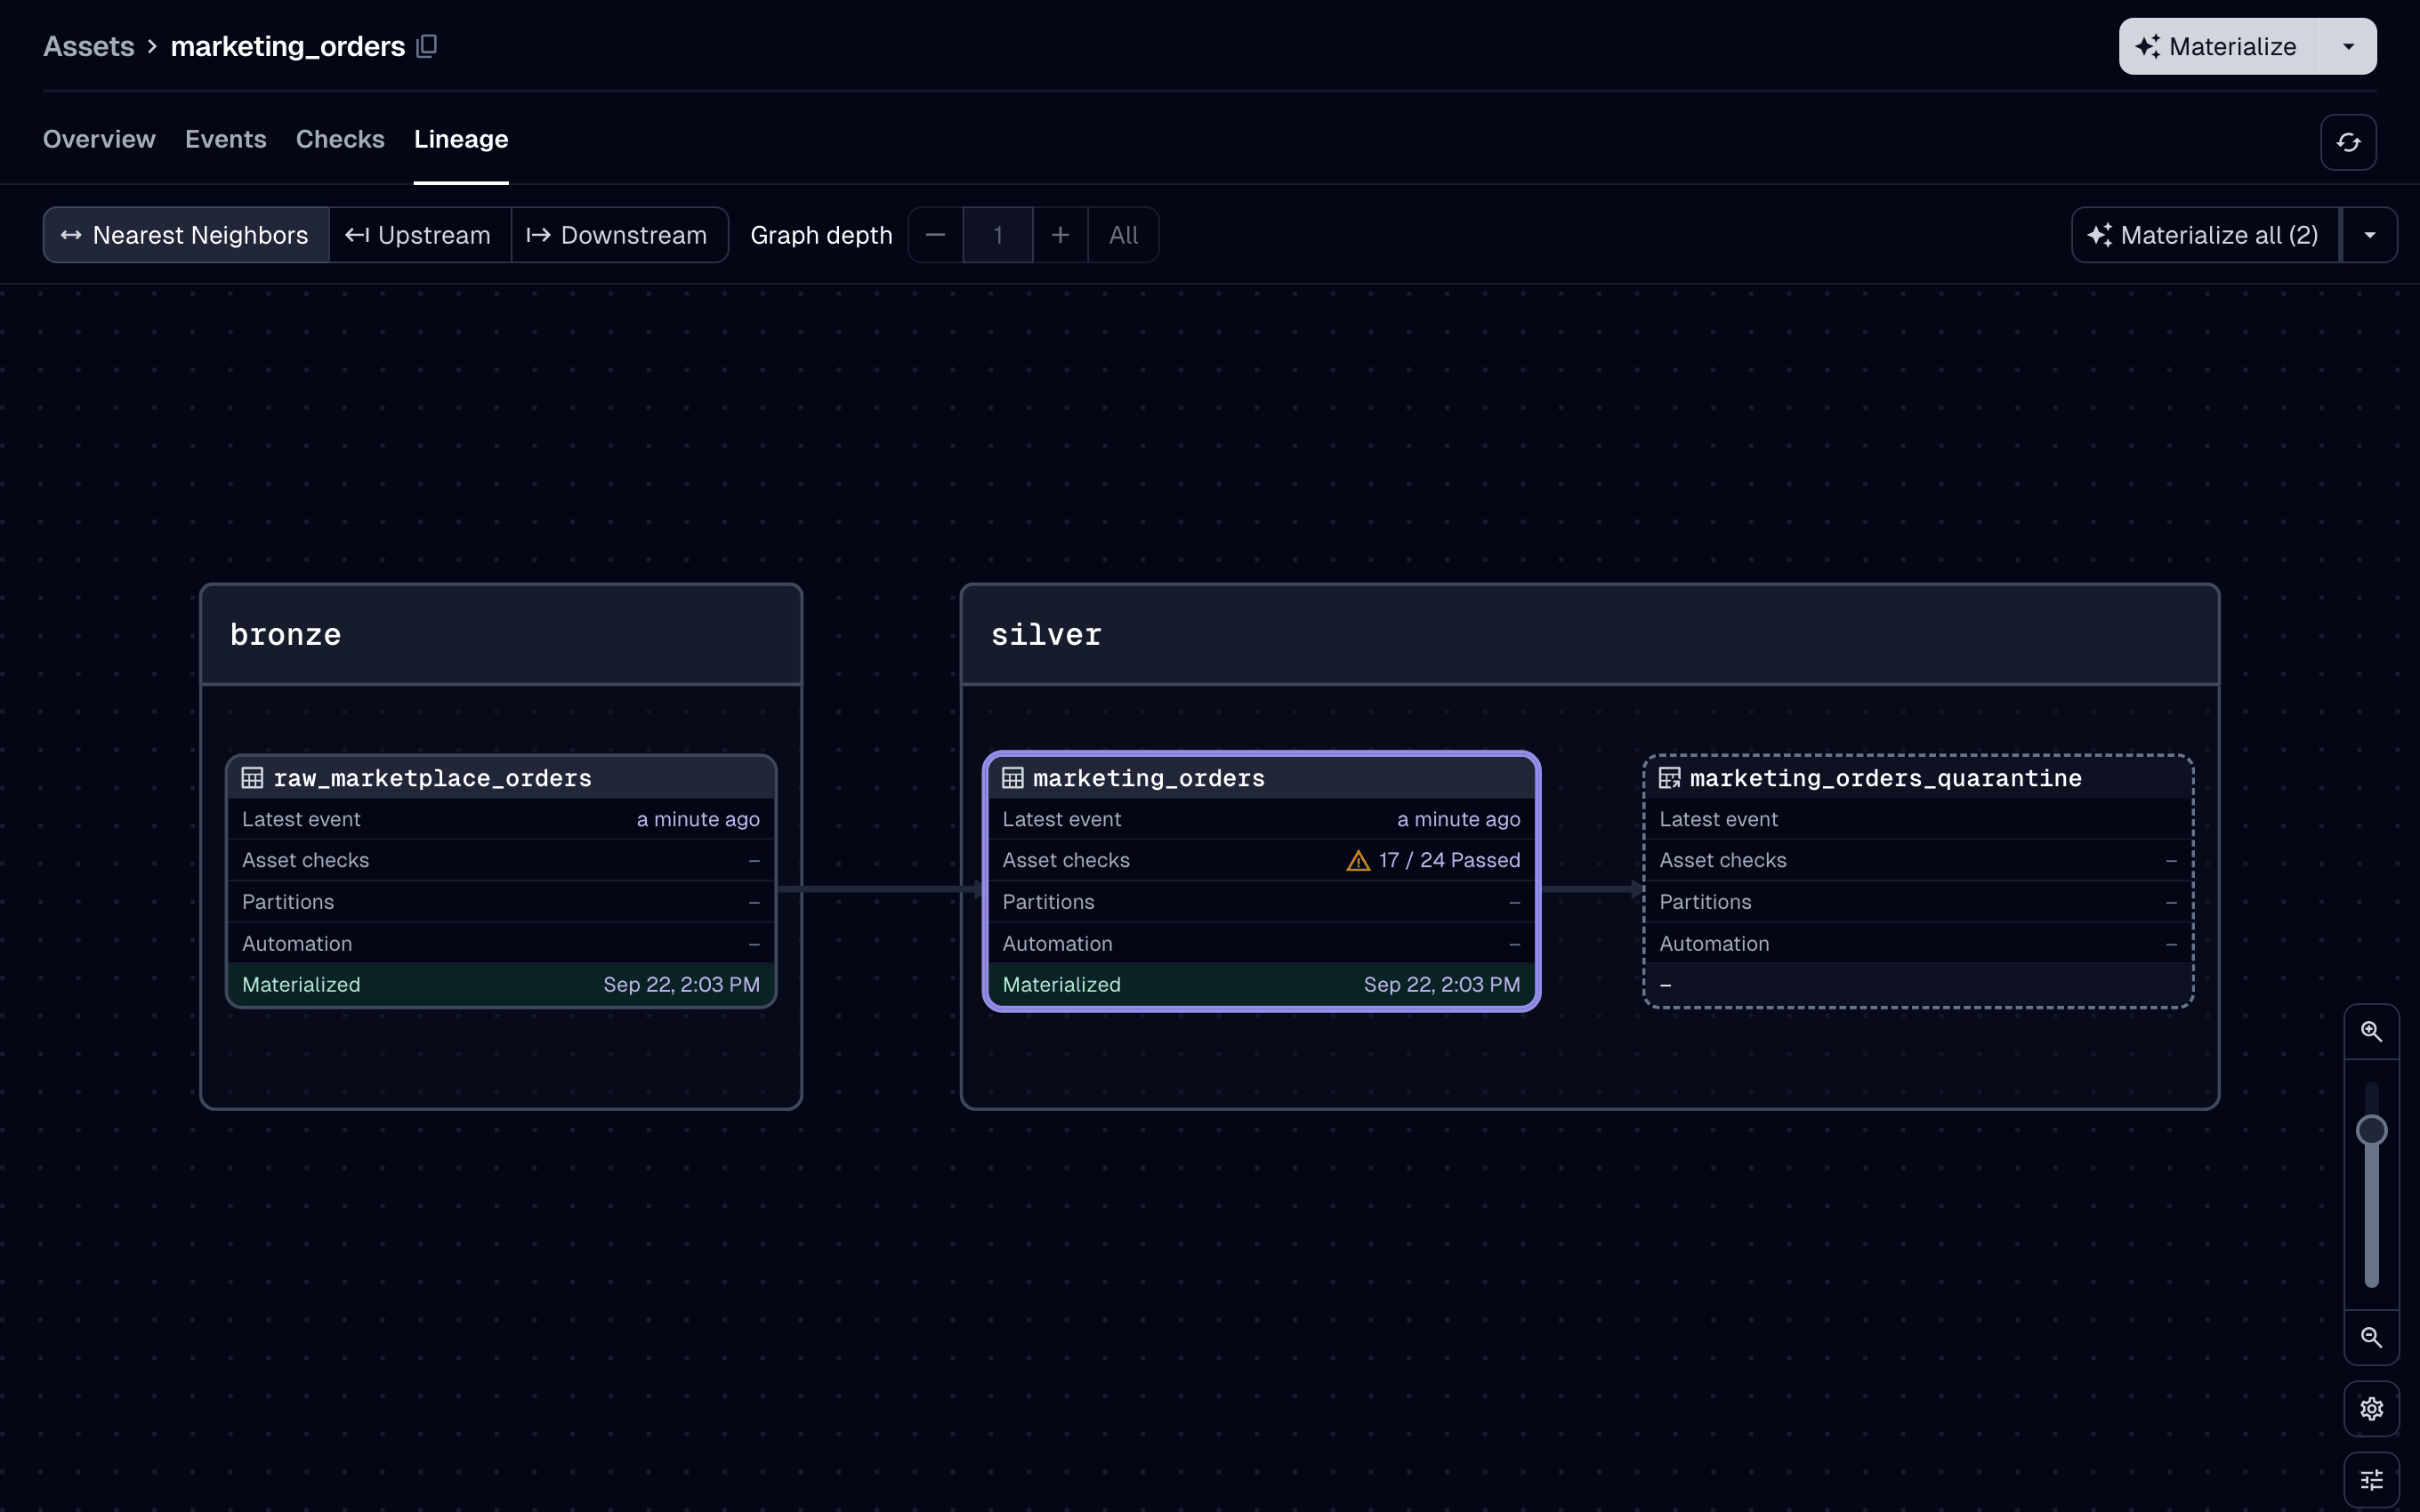
The lineage view. The table materialized with 17 of its 24 checks passing. Its quarantine is a separate node beside it, drawn with a dashed outline because nothing materializes it: the table’s own step wrote the invalid rows.
The decorated function is a normal Dagster asset function. Dagster passes upstream assets to it as parameters. It can also declare a context parameter. It returns a pl.DataFrame or a pl.LazyFrame, a dg.MaterializeResult whose value is one of those, or None.
dd.asset builds a @dg.asset and accepts its parameters under the same names. It leaves out six, which it sets itself or does not support. The user guide lists them. A test fails if @dg.asset adds a parameter that dd.asset lacks, or removes one that dd.asset passes on.
Package philosophy
Schema on write. Validation happens when an asset writes a table, never when it reads one. The checks run before the IO manager receives the frame, so it never writes a failing row to the table.
Use this package after ingestion, from bronze to silver to gold, to check that data is fit to publish. Load raw records with a permissive loader such as dlt, and declare a schema on the first table that other people query. Use another tool for ingestion-scale or larger-than-memory data.
The decorated function must return the schema’s dtypes. A dtype that differs from the schema’s fails the run, and the package never casts it. There is no lenient mode. Extra columns and column order need no extra work: Schema.filter drops the columns the schema does not declare and returns the rest in the schema’s order. So dtypes are the only thing you have to fix.
Partial data needs a declaration, not a setting. The only parameter for it is quarantine=True. No environment variable sets it. Without it, one failing row fails the run and the package writes nothing, so your last-known-good table is unchanged.
The decorator is strict, but you can use its parts without it. The package builds dd.asset from parts that it also exports under dd.wiring. Each part adds one feature to an asset that dd.asset cannot build: the Columns tab for an asset that writes its own storage, or the checks for a table that something else already wrote.
Quick start
uv add dagster-dataframelyYou need Python 3.12 or newer.
The dependencies are dagster, dataframely and polars, plus universal-pathlib, which dagster already installs.
This package does not include an IO manager. dagster-polars writes Polars frames to a filesystem or object store, and dagster-duckdb-polars writes them to a warehouse. Any IO manager that stores by asset key works.
Pre-1.0. A characterization test covers the public surface, so it never changes by accident. It can still change: a
0.xminor release can include breaking changes. If that matters to you, pin to one minor version:>=the version you installed,<the next minor. If you are upgrading from 0.8 or earlier, read the changelog first.
Declare the schema and the asset as above, then bind an IO manager. In a dg project, Dagster loads every module under defs/ automatically, so the IO manager needs one more file:
import dagster as dg
from dagster_polars import PolarsParquetIOManager


@dg.definitions
def resources() -> dg.Definitions:
    """Bind the Parquet IO manager the pipeline writes through."""
    return dg.Definitions(
        resources={"io_manager": PolarsParquetIOManager(base_dir="storage")}
    )
customers reads raw_customers, so the asset that produces raw_customers goes under defs/ too. Run dg dev and materialize both from the UI.
Four things now exist that did not before:
- The catalog’s Columns tab, filled from
Customers, before the first run. - One asset check per rule, each with its own history, evaluated on every run.
- A materialization that has the row count, a row sample and statistics for each dtype group.
- A table, written by your IO manager.
To write the rows that fail to a quarantine instead of failing the run, declare @dd.asset(Customers, quarantine=True). The same IO manager writes them, under the asset’s key with _quarantine appended. Each of those rows has one added column per rule, which shows whether the row failed that rule. The checks then fail at WARN and the run succeeds, so downstream assets read the valid rows.
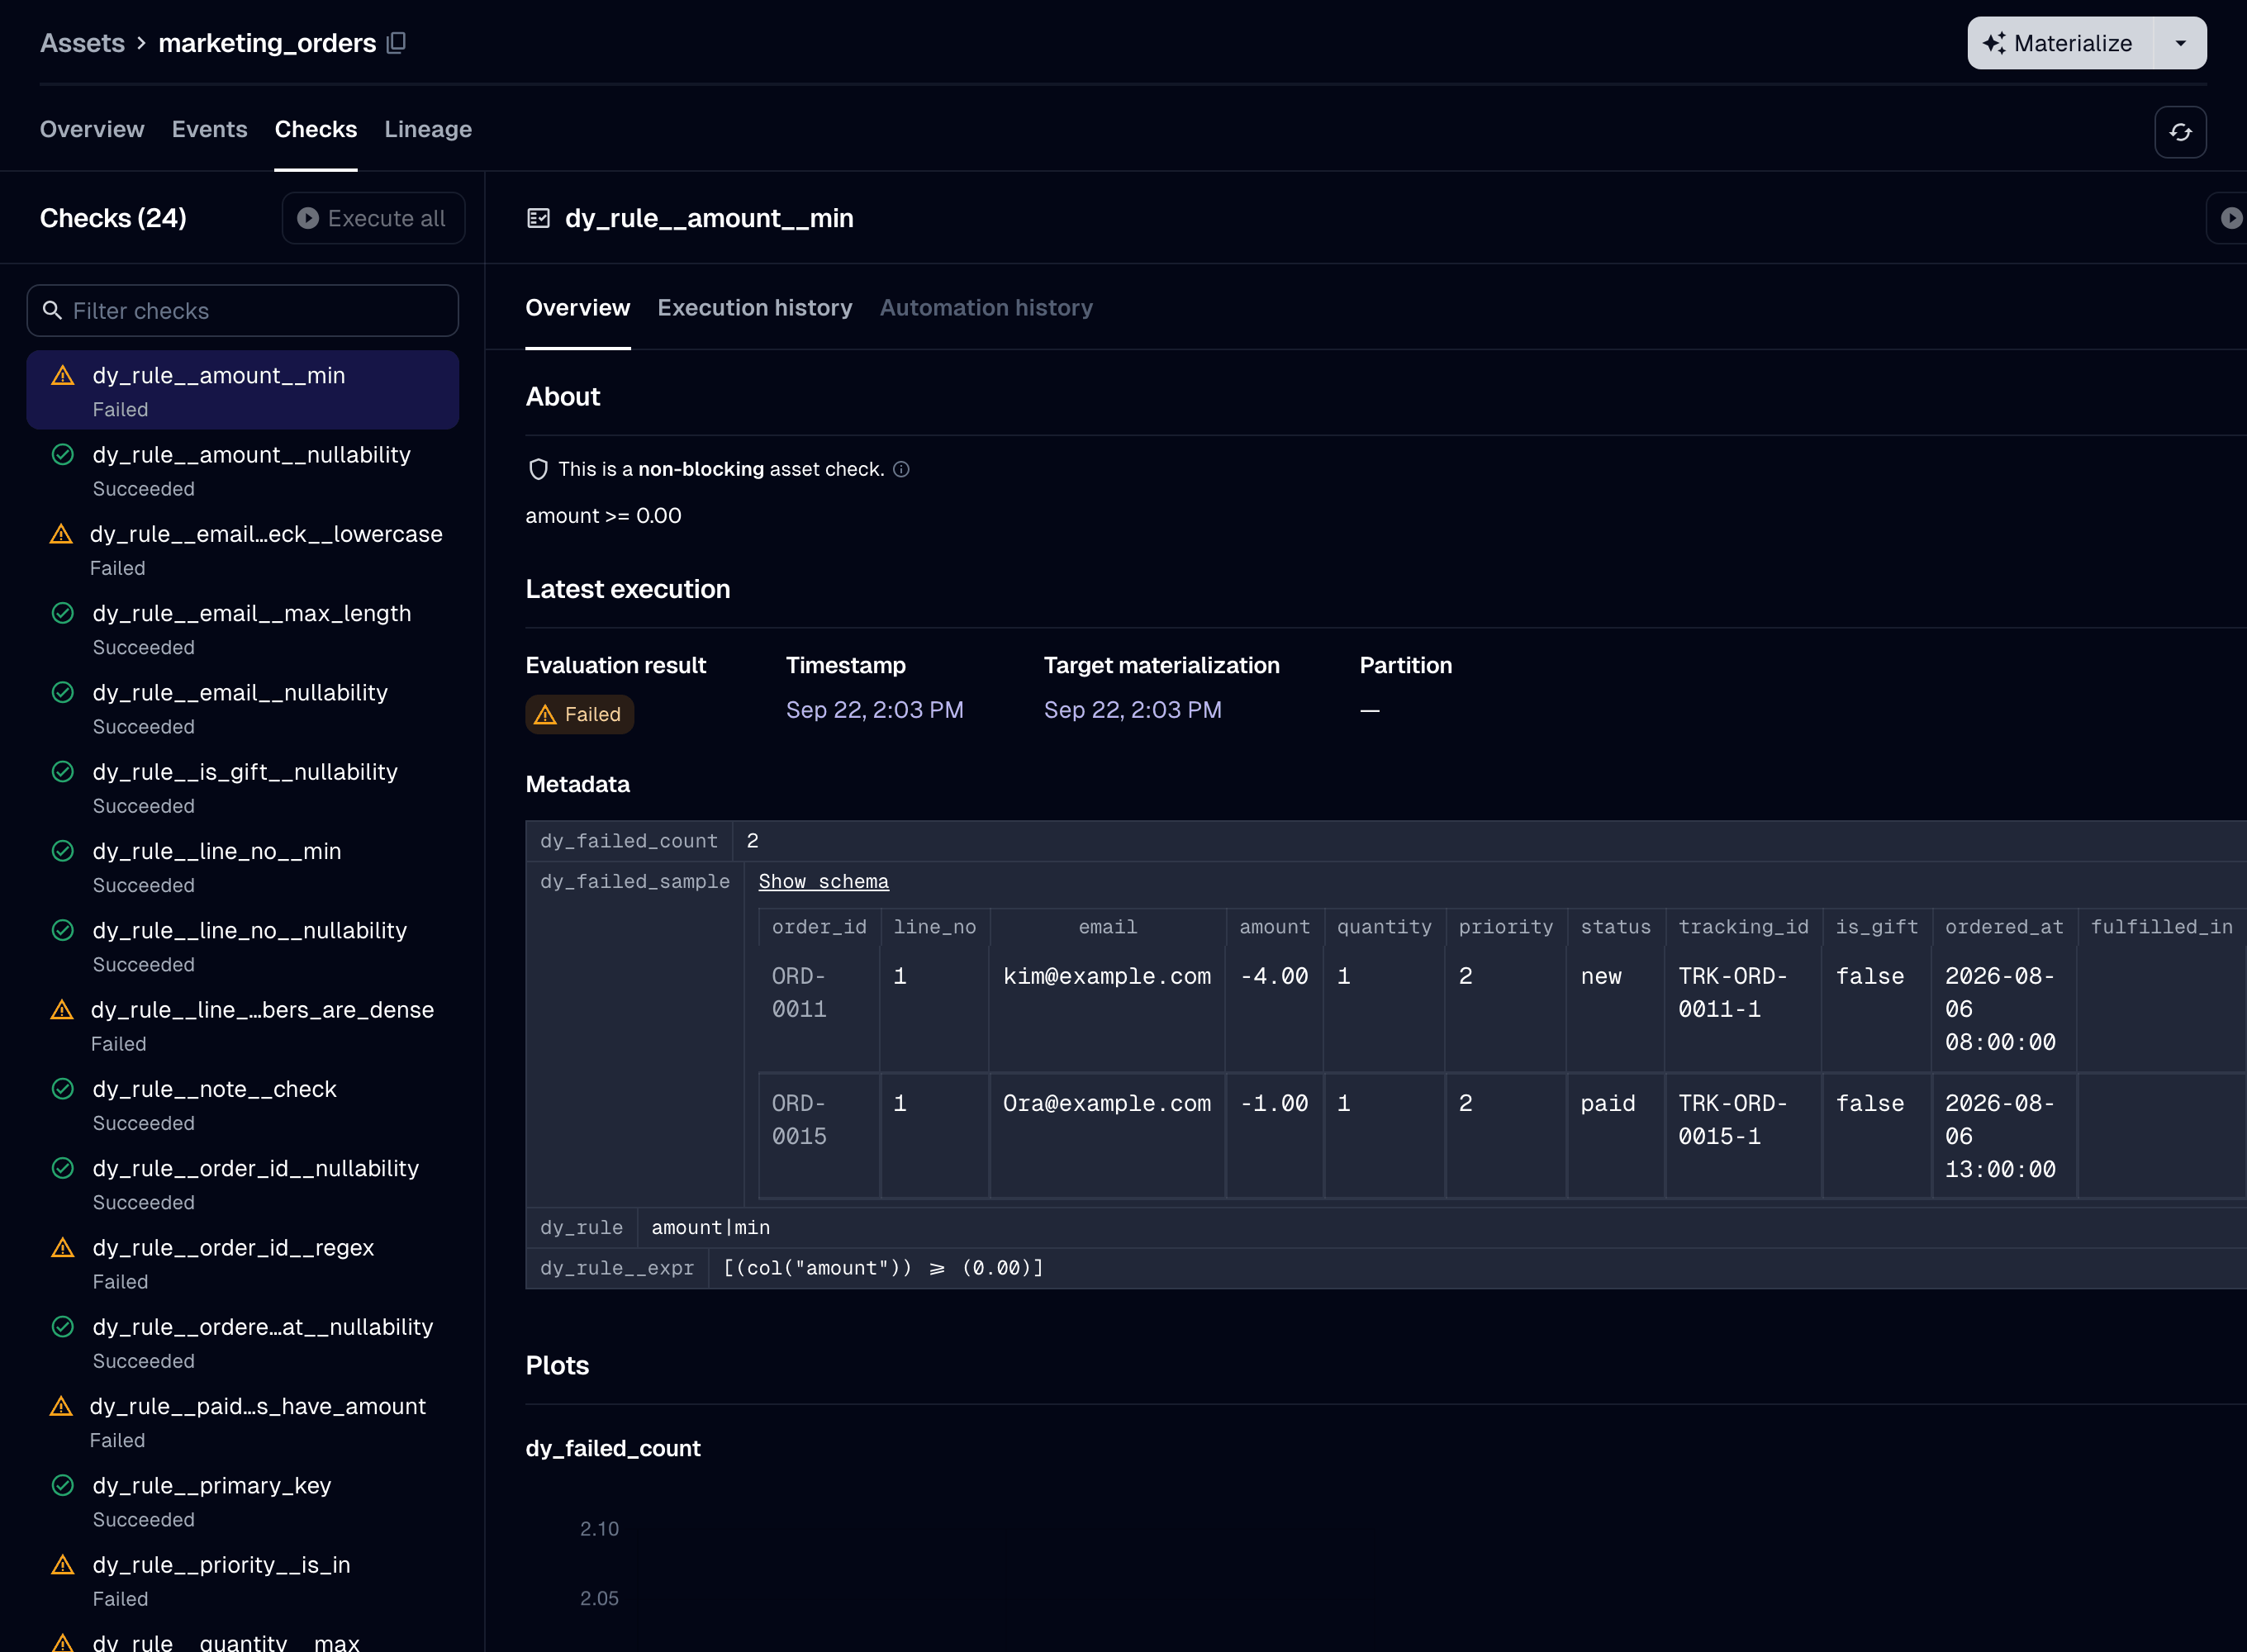
quarantine=True has seven of its twenty-four checks failing at WARN. The selected check shows its rendered constraint, the rule’s expression, and the two rows that failed the rule.Documentation
https://ozanozbeker.com/dagster-dataframely has the guide, the API reference and the changelog. The site is for users. Contributor documentation stays in the repository: CONTEXT.md is the glossary, and docs/pre-1.0.md records the decisions and the measurements the package was built on.
License
Apache 2.0. See LICENSE.